
Claude Fable 5.2 is Anthropic’s most capable public model, and it is 20% cheaper than the one it replaces. It scores 49.1% on FrontierCode 2.0, the test of whether an agent’s code would be merged, against Fable 5.1’s 32.4%. On the Remote Labor Index, built from real freelance projects, it finishes 41.3% to a professional standard against 17.9%. And it costs $8 per million input tokens and $40 per million output tokens, against $10 and $50. The top of Anthropic’s range got better and cheaper in the same release.
Anthropic released Claude Fable 5.2 and Claude Mythos 5.2 on 9 November 2026, ten weeks after Fable 5.1. The two names are one underlying model. Fable 5.2 carries cybersecurity and biology safeguards and is open to everyone. Mythos 5.2 loosens those safeguards and is limited to organisations vetted through Anthropic’s verification programmes. Both produce output up to 30% faster than their predecessors, and both gain an optional fast mode that runs up to 2.5 times quicker for double the price.
It is not the model Anthropic wants you to use for everything. Its own advice is to start with Claude Opus 5.5, which costs half as much, and to move up only when the work is long, open-ended and technical. Opus 5.5 still leads on two knowledge work ratings, Google’s Gemini 4 Carbon edges it on business workflows, and its top effort setting can cost more and score less than the one below it. Below you will find every launch benchmark, the main results from the system card, the cost per task at each effort level, full pricing with fast mode, how Fable 5.2 differs from Mythos 5.2, and what it means for finance and accounting teams.
Claude Fable 5.2: the short answer
Claude Fable 5.2 against Fable 5.1, Claude Opus 5.5 and GPT-6 Astra:
Scores from Anthropic’s launch page, at the effort settings it reports (see the fine print below), with Humanity’s Last Exam run with tools. Teal marks the best value in each row. Prices are per million input and output tokens, from each vendor’s price list on 10 November 2026.
| Fact | Claude Fable 5.2 |
|---|---|
| Released | 9 November 2026 |
| Family | The third Fable release, after Fable 5 (9 June) and Fable 5.1 (1 September); the same underlying model as Claude Mythos 5.2 |
| Model ID | claude-fable-5-2 (Amazon Bedrock: anthropic.claude-fable-5-2); Mythos is claude-mythos-5-2 |
| Where you can use it | Claude API, Amazon Bedrock, Claude Platform on AWS, Google Cloud and Microsoft Foundry, plus the Claude apps on Pro, Max, Ultra, Team and Enterprise plans |
| Input / output price | $8 / $40 per 1M tokens (Fable 5.1: $10 / $50) |
| Fast mode | $16 / $80 per 1M tokens, for up to 2.5 times the output speed |
| Cache reads | $0.20 per 1M tokens (Fable 5.1: $0.25) |
| Cache writes | $10 per 1M tokens for 5 minutes, $16 for 1 hour |
| Batch processing | Half price: $4 / $20 per 1M tokens |
| Context window | 1M tokens, at the standard price throughout |
| Max output | 128K tokens |
| Input and output | Text and images in, text out |
| Knowledge cutoff | June 2026 |
| Thinking | Adaptive thinking, always on |
| Effort levels | Low, medium, high, xhigh and max. High is the API default; medium is the default in the Claude apps and Claude Code |
| Data retention | 30 days required. Not available under zero data retention unless Anthropic authorises it |
| Retirement | Not before 9 November 2027 |
| Open weights | No. It is available only through Anthropic’s API, apps and cloud partners |
If you already run Fable 5.1, the move is easy to justify: Fable 5.2 is ahead on every row of Anthropic’s launch table and costs 20% less per token. If you run Opus 5.5, it is a closer call, and the cost per task section below is the place to look. For how these models rank on independent tests, see our live AI leaderboard. We will add Fable 5.2 there once independent scores are in.
Prefer to watch? Here is Claude Fable 5.2 in two minutes: the price cut, the launch benchmarks, where it does not lead and which Claude model to use.
What is new in Claude Fable 5.2
Anthropic describes Fable and Mythos as its models for the most daunting technical challenges. Against Fable 5.1, eight things changed:
- A real jump in capability. FrontierCode 2.0 rises from 32.4% to 49.1%, the Remote Labor Index from 17.9% to 41.3%, and RoboDojo robot control from 27.6% to 64.9%. Anthropic says the pair sit a step above Opus 5.5 on almost every capability it evaluated.
- A lower price. Input falls from $10 to $8 per million tokens and output from $50 to $40. Cache reads fall with it, from $0.25 to $0.20.
- More speed, and a fast mode. Output arrives up to 30% faster than on Fable 5.1. A new fast mode raises output speed by up to 2.5 times for $16 and $80 per million tokens. Fable 5.1 had no fast mode.
- Clearer writing. Testers found that the new models communicate more clearly than earlier Fable and Mythos models.
- Fewer false alarms. In early testing across claude.ai, Claude Code and Cowork, Anthropic saw about 55% fewer safeguard blocks than with Fable 5.1: about 60% fewer in cybersecurity and 40% fewer in biology.
- More from each effort level. At medium effort it finishes hard tasks with fewer tokens than Fable 5.1. At high effort it comes within 0.2 points of Opus 5.5’s best FrontierCode score for roughly half the cost per task.
- Work at the scale of a thousand agents. A team of 1,000 Fable 5.2 agents formalised the proof of Fermat’s Last Theorem in 30 hours. It can also act as an advisor that smaller models consult, or as the orchestrator that hands work to them.
- Stronger defences against copying. Anthropic says Fable 5.2 has its strongest protections yet against distillation, and a related API rule, preserved thinking, now applies to every account. Developers should read the migration section below.
Anthropic backs the claims with work it did before release. It says a team of agents on an earlier version moved a production service from Python to Rust, and the service now starts about 26 times faster. One engineer had the model build a prototype operating system from an empty folder: it coordinated over 1,000 subagents for eight days and produced a system that boots on a laptop. Given a one-paragraph prompt, it designed three working electronic devices, each with a circuit board that was ready for manufacturing in under a day. It also solved two open problems in the physics of black holes, and Anthropic links to preprints of both results.
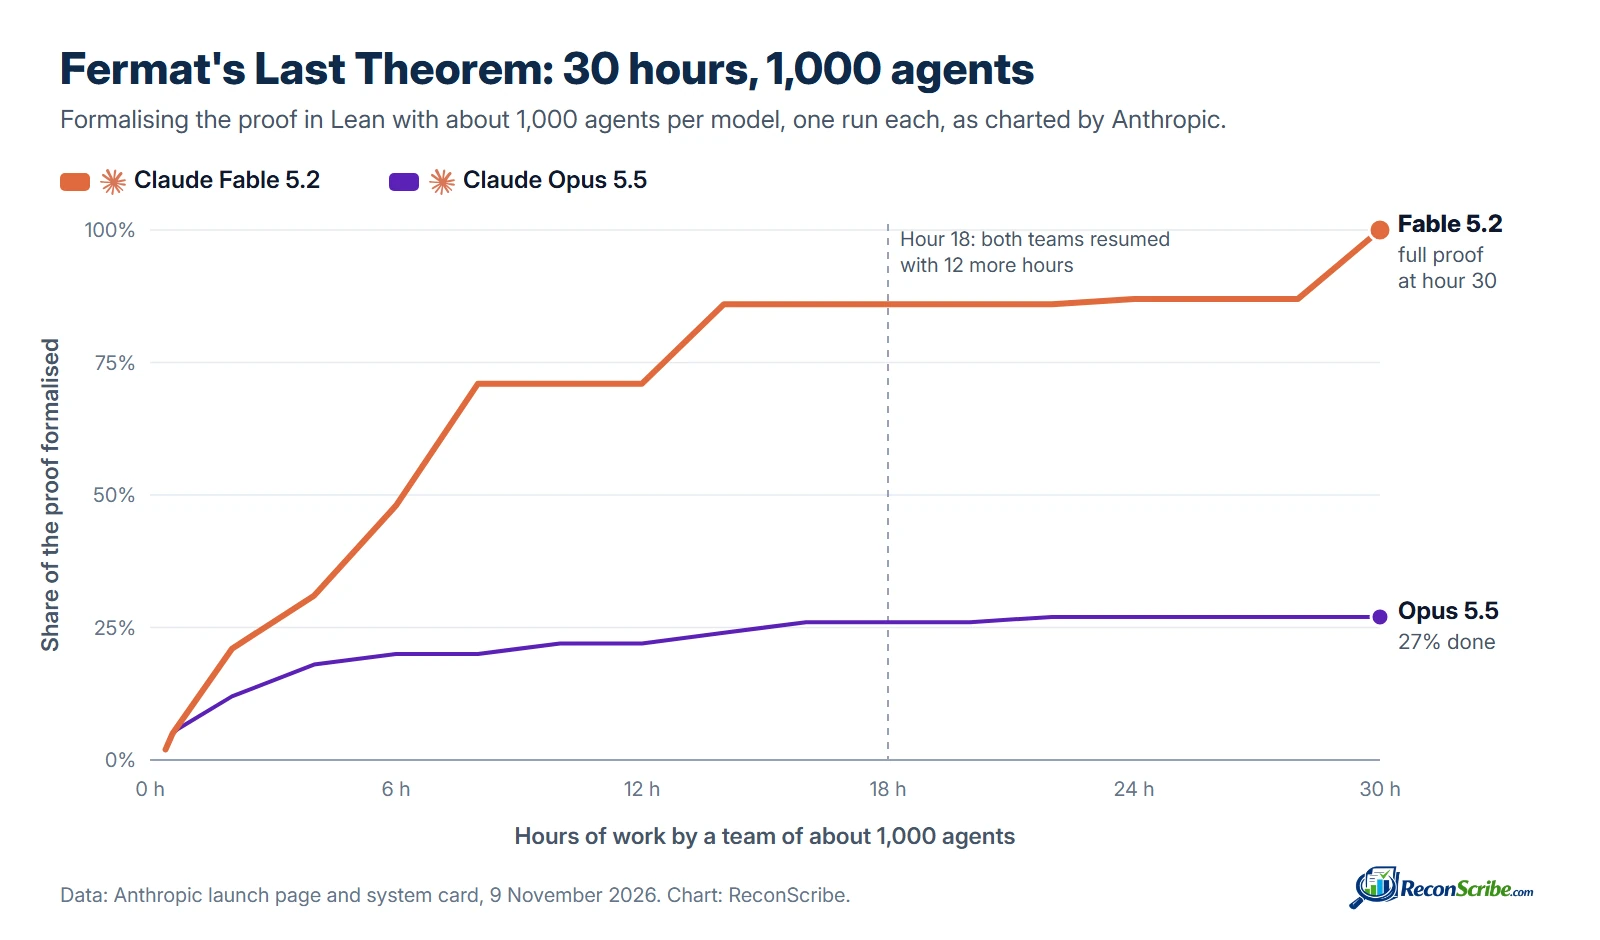
| Hours worked | Claude Fable 5.2 | Claude Opus 5.5 |
|---|---|---|
| 2 | 21% | 12% |
| 6 | 48% | 20% |
| 8 | 71% | 20% |
| 14 | 86% | 24% |
| 18 | 86% | 26% |
| 24 | 87% | 27% |
| 30 | 100% | 27% |
The Fermat result is the clearest picture of what changed. Anthropic’s first formalisation of the theorem, by an unreleased research model, took 11 days and a purpose-built harness. The Fable 5.2 team did it in 30 hours from minimal prompts, used one-third as many action tokens and produced a proof seven times shorter. With the same set-up, Opus 5.5 completed 26% in 18 hours and barely moved after that. Two cautions from the system card: both teams started from the definitions and supporting lemmas of Anthropic’s earlier formalisation, and the run used an earlier snapshot of the model, once per model.
Fable 5.2 vs Mythos 5.2: who gets which
Anthropic ships its strongest model in two forms. The capabilities are the same; the difference is what the safeguards allow and who is let in.
| Claude Fable 5.2 | Claude Mythos 5.2 | |
|---|---|---|
| Who can use it | Everyone: API customers and paid Claude plans | Organisations vetted through Anthropic’s Cyber and Life Sciences Verification Programmes |
| Safeguards | Classifiers block high-risk cybersecurity work and most research biology; in the Claude apps a blocked request is answered by an older model | More permissive in those two areas |
| Price per 1M tokens | $8 / $40 | $8 / $40 |
| Fast mode | Yes, $16 / $80 | Yes, for verified organisations only |
| Model ID | claude-fable-5-2 |
claude-mythos-5-2 |
| Where | Claude API, Amazon Bedrock, Claude Platform on AWS, Google Cloud, Microsoft Foundry and the Claude apps | Claude API, Amazon Bedrock, Google Cloud and Microsoft Foundry |
| Also powers | The Fable option in the Claude apps and Claude Code | Claude Security, the code-scanning product open to every Claude Enterprise customer |
| Headline results | 49.1% on FrontierCode 2.0, 41.3% on the Remote Labor Index | 89.6% on CVE Rediscovery, 76.3% on CyScenarioBench, 85.1% on de novo binder design |
For most readers Mythos 5.2 is a model to know about, not one to use. Anthropic calls it its most capable model for cybersecurity engineering. On CVE Rediscovery, its internal test built from 1,829 real vulnerabilities published in October 2026, Mythos 5.2 found 89.6% against 81.3% for Opus 5.5 and 78.3% for Mythos 5.1, all with safeguards off. Security teams can apply through the Cyber Verification Program, and life sciences researchers through the Life Sciences Verification Program. Everyone else gets the same model as Fable 5.2, with those two doors closed.
Claude Fable 5.2 benchmarks: the official launch table
Here are the launch benchmarks exactly as Anthropic published them, with a plain note on what each test measures. Anthropic compares Fable 5.2 with Fable 5.1, Opus 5.5, OpenAI’s GPT-6 Astra and Google’s Gemini 4 Carbon:
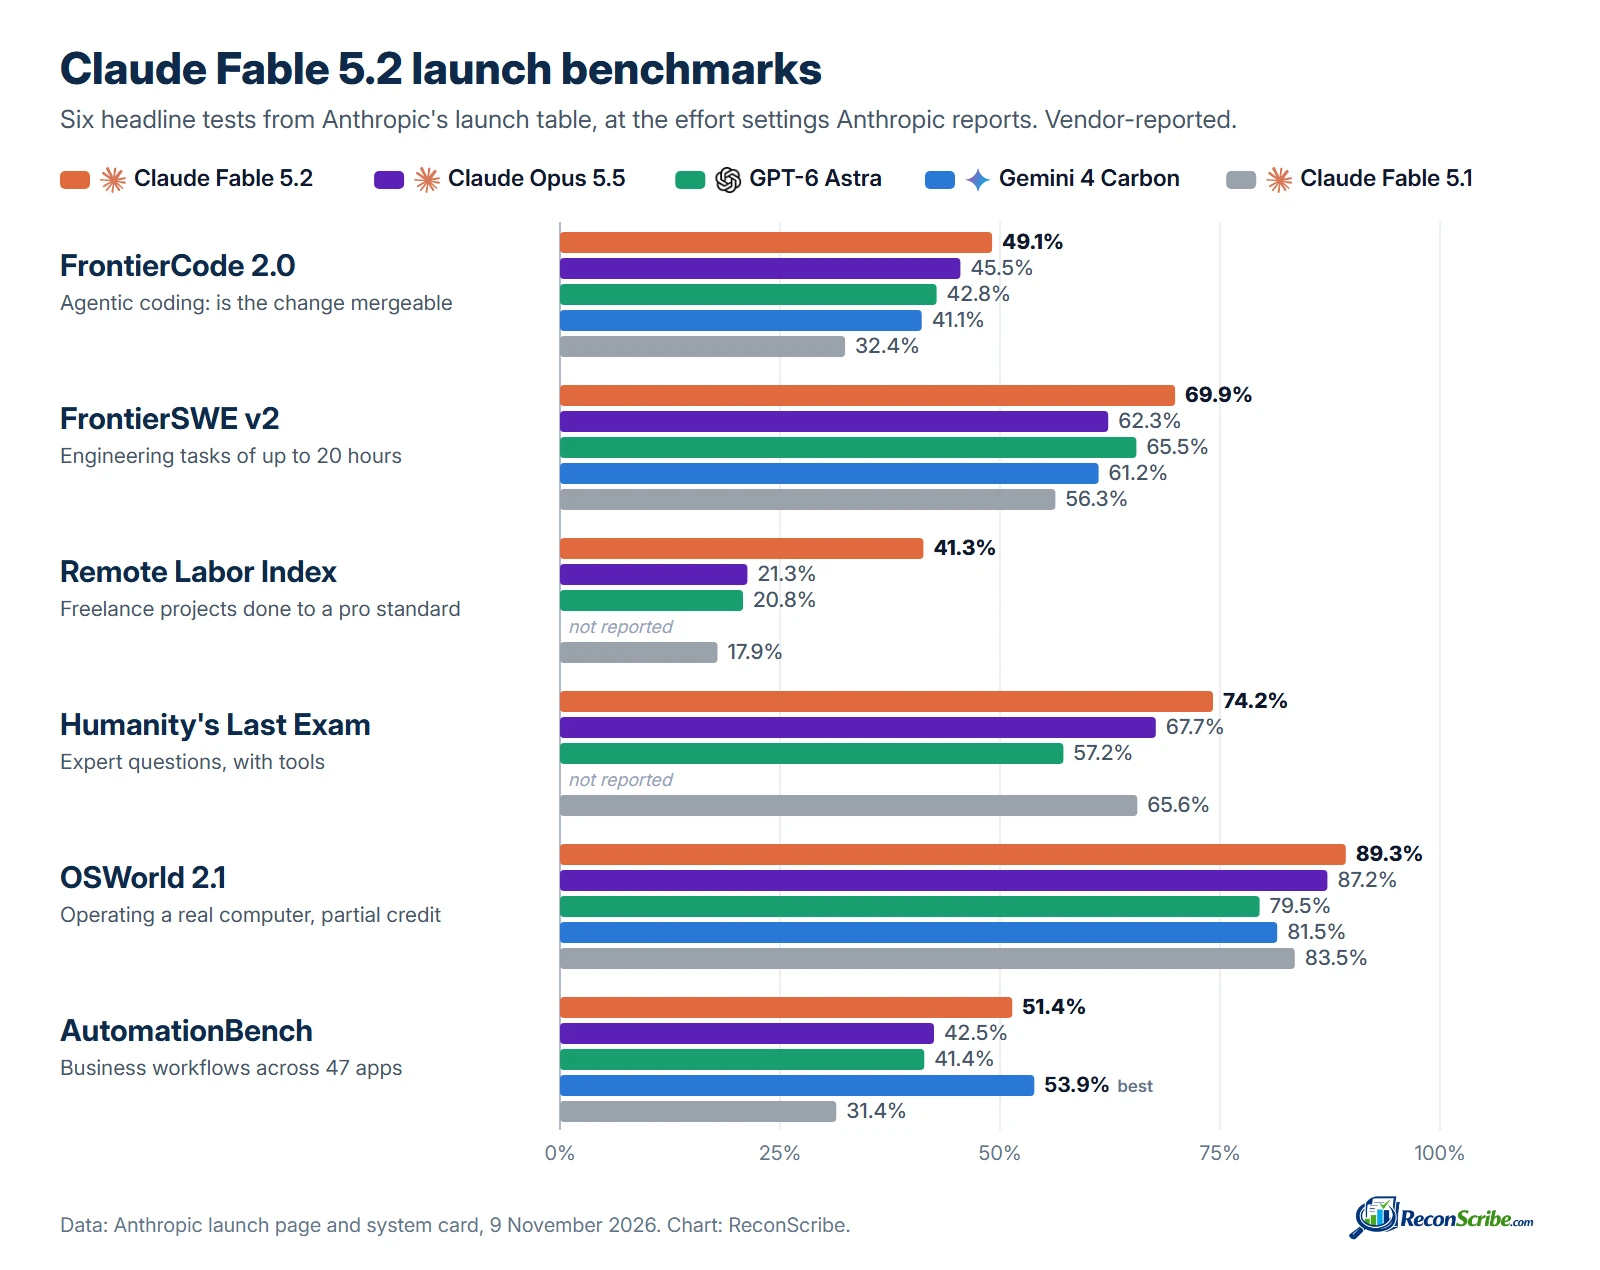
| Benchmark | What it tests | Fable 5.2 | Fable 5.1 | Opus 5.5 | GPT-6 Astra | Gemini 4 Carbon |
|---|---|---|---|---|---|---|
| FrontierCode 2.0 | Agentic coding: would maintainers merge the code change | 49.1% (xhigh) | 32.4% (xhigh) | 45.5% | 42.8% | 41.1% (medium) |
| FrontierSWE v2 | Very long engineering and research tasks, up to 20 hours each | 69.9% | 56.3% | 62.3% | 65.5% | 61.2% |
| AutomationBench | End-to-end business workflows across 47 apps | 51.4% | 31.4% | 42.5% | 41.4% | 53.9% |
| Terminal-Bench-Science 0.1 | Scientific research tasks in a terminal | 74.6% (Mythos 5.2: 75.3%) | 52.6% | 58.7% | 68.1% | 64.8% |
| WANDR (relaxed score) | Collecting facts on hundreds of items, with citations | 82.1% | 68.7% | 72.3% | not reported | not reported |
| OSWorld 2.1 (offline set, partial) | Operating a real computer through long tasks | 89.3% | 83.5% | 87.2% | 79.5% | 81.5% |
| RoboDojo Sim | Controlling a simulated two-arm robot from camera images | 64.9% | 27.6% | 39.4% | 29.8% | not reported |
| AA-Briefcase v1.1 (rubric) | Multi-week knowledge work projects, rubric pass rate | 66.1% | 61.5% | 61.2% | 52.0% | 61.8% |
| AA-Briefcase v1.1 (Elo) | The same projects, rated by pairwise comparison | 1785 | 1669 | 1800 | 1569 | 1611 |
| Remote Labor Index | Real freelance projects done at least as well as a professional | 41.3% (high) | 17.9% | 21.3% | 20.8% | not reported |
| Humanity’s Last Exam (with tools) | Expert questions across dozens of subjects | 74.2% | 65.6% | 67.7% | 57.2% | not reported |
| Chartography (no tools) | Reading specialised charts and figures | 73.4% | 44.8% | 64.4% | 71.0% | 72.5% |
| CyScenarioBench | Cybersecurity scenarios (each lab’s scores use its own tasks) | 76.3% (Mythos 5.2) | 61.7% (Mythos 5.1) | 67.6% (no safeguards) | 61% (GPT-6 Cyber) | not reported |
| CVE Rediscovery | Finding 1,829 real, published vulnerabilities | 89.6% (Mythos 5.2) | 78.3% (Mythos 5.1) | 81.3% (no safeguards) | not reported | not reported |
| De novo binder design (24 hr) | Designing protein binders in a 24-hour campaign | 85.1% (Mythos 5.2) | 79.1% (Mythos 5.1) | 82.6% (no safeguards) | not reported | not reported |
Where Claude Fable 5.2 beats GPT-6 Astra
GPT-6 Astra is the OpenAI model in Anthropic’s table and Fable’s most direct rival on price. On that table, Fable 5.2 leads it on every row where both are scored: 49.1% against 42.8% on FrontierCode 2.0, 69.9% against 65.5% on FrontierSWE v2 and 74.6% against 68.1% on Terminal-Bench-Science. It is also ahead on OSWorld, 89.3% against 79.5%, and on Humanity’s Last Exam with tools, 74.2% against 57.2%. The widest gaps are on work that looks least like a chat: 41.3% against 20.8% on the Remote Labor Index and 64.9% against 29.8% on RoboDojo. The narrowest is chart reading, 73.4% against 71.0%. Fable 5.2 is now also the cheaper of the two per token, at $8 and $40 against $10 and $50.
Where Opus 5.5 and Gemini 4 Carbon still lead
Two rows of the launch table do not go Fable 5.2’s way. On AutomationBench, Zapier’s test of end-to-end business workflows, Gemini 4 Carbon scores 53.9% against 51.4%. On AA-Briefcase, Opus 5.5 holds the higher Elo rating, 1800 against 1785, even though Fable 5.2 has the best rubric score at 66.1%. The system card adds a third: on GDPval-AA, the rating built on real professional work, Opus 5.5 leads 1866 to 1831, and Meta’s Muse Wonder Full sits between them at 1857.
Carbon needs a caveat. Google announced Gemini 4 Carbon on 28 October 2026 and has so far opened it only to a subset of cyber defenders and trusted partners, so most teams cannot buy it yet. It appears on 7 of the 14 tests in Anthropic’s table. Where it is scored, it is close: within 2.5 points of Fable 5.2 on AutomationBench and Chartography, and 8 points behind on FrontierCode at the medium setting Anthropic reports for it.
The fine print behind the table
- Scores for Fable 5.2, Fable 5.1 and Opus 5.5 were run with safeguards on unless a row says otherwise, at each model’s highest available effort unless the table names another setting.
- FrontierCode 2.0 is run by Cognition, its maker, for every model. Fable 5.2’s 49.1% is at xhigh. At max it scored 45.6% on Anthropic’s chart (45.7% in the system card’s text), and 22 of its 660 max attempts timed out; counting those as zero gives 44.4%, below Opus 5.5’s 45.5%.
- Each FrontierCode score is a single result with no error bar. Anthropic itself warns that small gaps, such as 0.2 points, may not be meaningful.
- Anthropic ran GPT-6 Astra’s OSWorld test itself, on the same 82 offline tasks, through OpenAI’s API. Astra’s Terminal-Bench-Science score is the one OpenAI reported.
- Scale AI ran the Remote Labor Index with each Claude model at default settings: high effort, a 200K token context window and 32K tokens per response.
- RoboDojo Sim was run by Anthropic internally. On CyScenarioBench each lab’s scores are based on its own tasks, so that row is not a like-for-like comparison.
- Artificial Analysis ran AA-Briefcase independently, and Zapier ran AutomationBench on its private task set. Anthropic ran WANDR on a frozen copy of the web with its own grader, so those scores cannot be compared with Perplexity’s published ones.
More Claude Fable 5.2 benchmarks from the system card
The launch page shows 14 tests. Anthropic’s 264-page Claude Fable 5.2 and Claude Mythos 5.2 system card has many more. Its summary says Fable 5.2 scored highest on 14 of the 16 results in its headline table, trailing Opus 5.5 on two Elo ratings. We cover the main results below and leave out a few specialist sets, such as the Mythos life science tests. First, the rows of the headline table that the launch page left out, at max effort:
| Benchmark | Fable 5.2 | Fable 5.1 | Opus 5.5 | GPT-6 Astra |
|---|---|---|---|---|
| SWE-bench Pro | 93.0% | 81.2% | 89.9% | not reported |
| SWE-bench Multilingual | 96.6% | 89.1% | 93.9% | not reported |
| SWE-bench Multimodal | 74.1% | 54.7% | 61.4% | not reported |
| Humanity’s Last Exam, no tools | 73.2% | 60.9% | 64.4% | not reported |
| Chartography, with tools | 91.6% | 88.4% | 89.0% | not reported |
| GDPval-AA v2.1 (Elo) | 1831 | 1763 | 1866 | 1584 |
Coding and agents
| Benchmark | What it tests | Claude Fable 5.2 | For comparison |
|---|---|---|---|
| DeepSWE v1.1 | 113 long software engineering tasks written from scratch | 74.3% | No comparison given |
| Terminal-Bench 4.0 | Hard, realistic work in a command line | 67.6%, safeguards on | Opus 5.5 66.4%, Fable 5.1 55.8%, GPT-6 Astra 57.9% as reported by OpenAI |
| CursorBench 4.0 | Real coding tasks in Cursor’s own agent harness | 60.0% at max, 56.9% at high | Opus 5.5 57.8%, Fable 5.1 51.8%, both at max |
| FrontierSWE v2 | 34 engineering tasks with a 20-hour budget each | 69.9% | GPT-6 Astra 65.5%, Opus 5.5 62.3%, Sonnet 5.5 61.9%, Gemini 4 Argon 55.0% |
| ProgramBench | Rebuilding a program from its binary inside one 1M token context | 85.6% | Opus 5.5 91.2%, Fable 5.1 87.6% |
| Large agent teams | Proving Fermat’s Last Theorem in Lean with 100 agents in 18 hours (score from 0 to 1) | 0.35 | Opus 5.5 0.21 |
ProgramBench is the one coding test where Fable 5.2 trails both Opus 5.5 and its own predecessor, and the reason is useful. The harness gives the model one 1M token context and does not say how much is left. Fable 5.2 ran out of context before submitting on 68% of tasks, against 39% for Opus 5.5. When the harness showed the tokens remaining after each step, it scored 91.6%, level with Opus 5.5’s 91.1%. On long jobs, show the model how much context it has left. Cursor’s result carries its own note: about 99,000 output tokens per task at high effort against about 353,000 at max, for a 3.1 point gain.
Two leads in this table are thinner than they look. The 1.2 point margin over Opus 5.5 on Terminal-Bench 4.0 is inside the margin of error. And Cursor credits part of Fable 5.2’s CursorBench score to its own prompt and harness improvements, so that figure is not a clean model-to-model comparison.
Office and knowledge work
| Benchmark | What it tests | Claude Fable 5.2 | For comparison |
|---|---|---|---|
| GDPval-AA v2.1 | Real professional work across 44 occupations (Elo) | 1831 | Opus 5.5 1866, Muse Wonder Full 1857, Fable 5.1 1763, GPT-6 Astra 1584 |
| AA-Briefcase v1.1 | Multi-week knowledge work projects with thousands of source files | 1785 Elo, 66.1% rubric | Opus 5.5 1800 and 61.2%, Fable 5.1 1669 and 61.5% |
| OfficeQA and OfficeQA Pro | Finding and calculating figures in US Treasury Bulletin documents | 83.4% and 72.9% | Fable 5.1 80.2% and 69.0%, Opus 5.5 78.9% and 67.7% |
| Real-World Finance v2 | Building and auditing financial models and client-ready work (Elo) | 1637 | Opus 5.5 1571, Fable 5.1 1493 |
| Legal Agent Benchmark (LAB-AA v1.1) | Legal tasks that meet every criterion with no material hallucination | 7.2% | GPT-6 Astra 8.6%, GPT-6.1 Sol 6.9%, Fable 5.1 6.4%, Opus 5.5 4.2% |
| AutomationBench | Business workflows across about 500 API endpoints in 47 apps | 51.4% at max, 39.7% at low | Opus 5.5 42.5% |
| Remote Labor Index | 240 real freelance projects judged against a professional’s work | 41.3% | Opus 5.5 21.3%, GPT-6 Astra 20.8%, Fable 5.1 17.9% |
This is the group where the two Elo ratings go to Opus 5.5, so read it carefully. Both ratings come from Artificial Analysis, which judges finished work side by side. On the same AA-Briefcase projects Fable 5.2 passes more rubric checks than any other model, which suggests it gets more of the checkable details right while the judging panel still prefers Opus 5.5’s finished product slightly more often. The legal benchmark is a reminder of how hard strict grading is: no model clears 9%, and GPT-6 Astra leads.
Reasoning and vision
| Benchmark | What it tests | Claude Fable 5.2 | For comparison |
|---|---|---|---|
| Humanity’s Last Exam | 2,500 expert questions across dozens of subjects | 73.2% without tools, 74.2% with | Opus 5.5 64.4% and 67.7%, Fable 5.1 60.9% and 65.6% |
| ARC-AGI-3 | Unfamiliar games with no instructions, scored on efficiency against people | 79.26% at high effort, standard harness | GPT-6 Astra 62.7%, GPT-6.1 Sol 52.7%, both at max |
| Chartography | Reading specialised charts such as candlestick and Sankey diagrams | 73.4% without tools, 91.6% with | Opus 5.5 64.4% and 89.0%, Fable 5.1 44.8% and 88.4% |
| BenchCAD 2.1 | Rebuilding parts and circuit boards from engineering drawings | 75.4% without tools, 83.5% with | Opus 5.5 49.0% and 65.3%, Fable 5.1 36.3% and 44.4% |
| OSWorld 2.1, strict pass | Computer tasks with every checkpoint satisfied | 54.6% | Opus 5.5 53.2%, Fable 5.1 47.6% |
Two details matter here. On ARC-AGI-3 the model did better at high effort than at max, 79.26% against 65.66%, another sign that more thinking is not always better. With the harness that lets each provider manage context its own way, Fable 5.2 reached 97.72%, but GPT-6 Astra reached 98.6%. And on OSWorld the strict pass rate of 54.6% is a more sober number than the 89.3% partial score in the launch table: it finishes every step of a long computer task a little over half the time.
Health and languages
| Benchmark | What it tests | Claude Fable 5.2 | For comparison |
|---|---|---|---|
| HealthBench | Health conversations, a benchmark from OpenAI run here by Artificial Analysis | 58.8% raw, 59.6% length-adjusted | Raw: Sonnet 5.5 65.9%, Opus 5.5 64.3%, Fable 5.1 63.9%, Haiku 5.5 61.2%, GPT-6 Astra 56.9%. Adjusted: Sonnet 5.5 62.1%, Opus 5.5 57.0% |
| HealthBench Professional | A second OpenAI health benchmark, also run by Artificial Analysis | 71.1% raw, 67.7% length-adjusted | Raw: Opus 5.5 71.4%, Sonnet 5.5 70.8%, GPT-6 Astra 69.7%, Fable 5.1 69.2%. Adjusted: GPT-6 Astra 66.0%, Sonnet 5.5 63.0%, Opus 5.5 59.9% |
| PhysicianBench | 100 physician tasks in an electronic health record | 64.4% | Opus 5.5 68.4%, Sonnet 5.5 63.2%, Fable 5.1 61.0% |
| GMMLU | Knowledge questions in 42 languages | 96.0% | Opus 5.5 94.3%, Fable 5.1 94.0%, Sonnet 5.5 92.1% |
| MILU | Knowledge questions in 11 languages, 10 of them Indic | 94.1% | Opus 5.5 93.1%, Fable 5.1 93.0%, Sonnet 5.5 91.6% |
Health is the one area with no clear gain. On raw HealthBench scores, Fable 5.2 sits below every other current Claude model, Haiku 5.5 included. The length-adjusted score, the form OpenAI reports, tells a different story: there it is second of six models at 59.6%, behind Sonnet 5.5, and on HealthBench Professional its adjusted 67.7% is the highest of the six. On PhysicianBench it trails Opus 5.5 by 4 points, a gap Anthropic says is within noise. Anthropic reports no confidence intervals for the two HealthBench tests. For multilingual work the picture is clearer: it is the top Claude model on both language tests.
Claude Fable 5.2 cost per task at every effort level
The single table hides the most useful part of this launch. Anthropic also published charts that plot each model’s score against the average cost of running one task, at every effort level. Higher effort means the model thinks and works for longer, so a task usually costs more and usually scores higher, though neither is guaranteed. The closer a point sits to the top left, the more you get per dollar.
High is the default effort on the Claude API, and medium is the default in the Claude apps and Claude Code, so those are the points most people will actually get. We turned the charts into tables below. First, the spread on one test. Here is what each effort level costs and scores on FrontierCode 2.0, the agentic coding test:
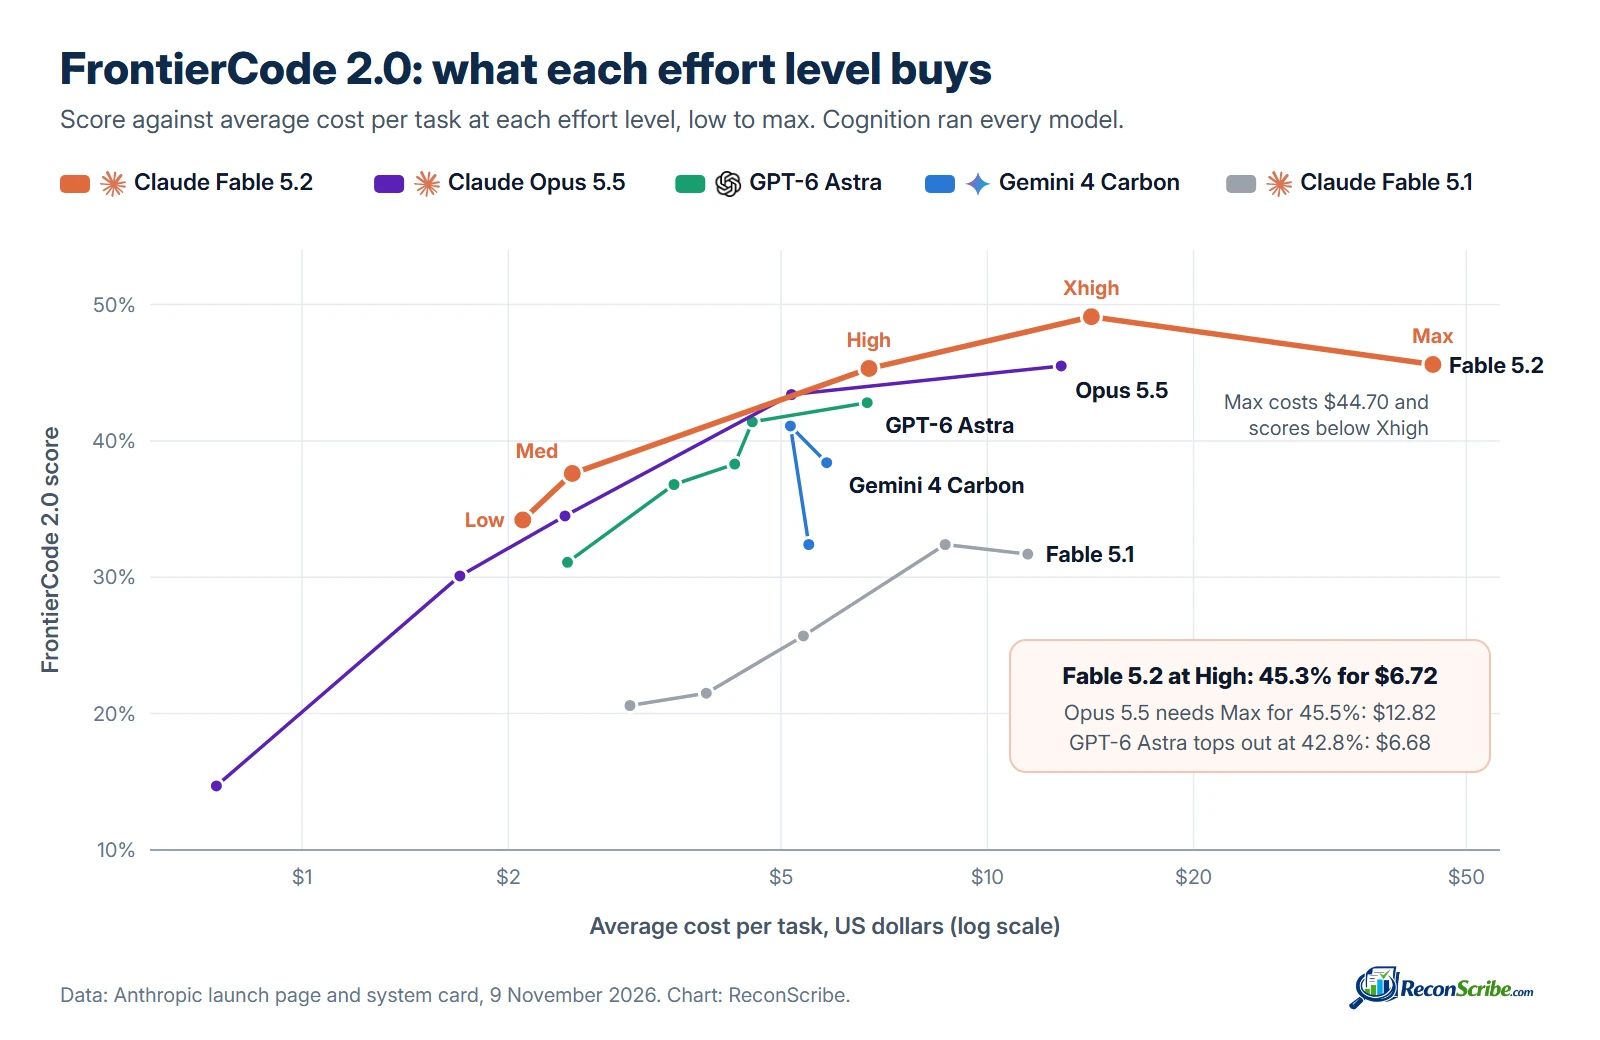
Claude Fable 5.2 average cost per task and score on FrontierCode 2.0 at each effort level, from Anthropic’s chart. High is the default on the API; medium is the default in the Claude apps and Claude Code.
FrontierCode 2.0: would the code be merged?
| Effort | Fable 5.2 | Opus 5.5 | GPT-6 Astra | Gemini 4 Carbon | Fable 5.1 |
|---|---|---|---|---|---|
| Low | 34.2% at $2.10 | 14.7% at $0.75 | 31.1% at $2.44 | 32.4% at $5.49 | 20.6% at $3.01 |
| Medium | 37.6% at $2.48 | 30.1% at $1.70 | 36.8% at $3.49 | 41.1% at $5.16 | 21.5% at $3.89 |
| High | 45.3% at $6.72 | 34.5% at $2.42 | 38.3% at $4.28 | 38.4% at $5.83 | 25.7% at $5.39 |
| Xhigh | 49.1% at $14.19 | 43.4% at $5.18 | 41.4% at $4.54 | not reported | 32.4% at $8.68 |
| Max | 45.6% at $44.70 | 45.5% at $12.82 | 42.8% at $6.68 | not reported | 31.7% at $11.46 |
This is the chart to study if you write software. At high, the API default, Fable 5.2 scores 45.3% for $6.72 a task. Opus 5.5 needs its max setting to reach 45.5%, and that costs $12.82, so Fable 5.2 gives about the same result for roughly half the money. GPT-6 Astra’s best is 42.8% for $6.68: the same spend for 2.5 points less. Xhigh lifts Fable 5.2 to 49.1%, the highest score of any released model Anthropic has tested, for $14.19.
Now the warnings. Max effort costs $44.70 a task, more than three times xhigh, and scores lower. There is also a gap in the middle: Fable 5.2 has no setting between $2.48 and $6.72 a task, and in that range GPT-6 Astra at xhigh (41.4% for $4.54) and Opus 5.5 at xhigh (43.4% for $5.18) are the better buys. At the cheap end it holds up: medium scores 37.6% for $2.48, ahead of Opus 5.5 at high, 34.5% for $2.42. And Fable 5.1 never gets above 32.4% at any price, which is the argument for moving off it.
Four more charts: research, reasoning, charts and hardware
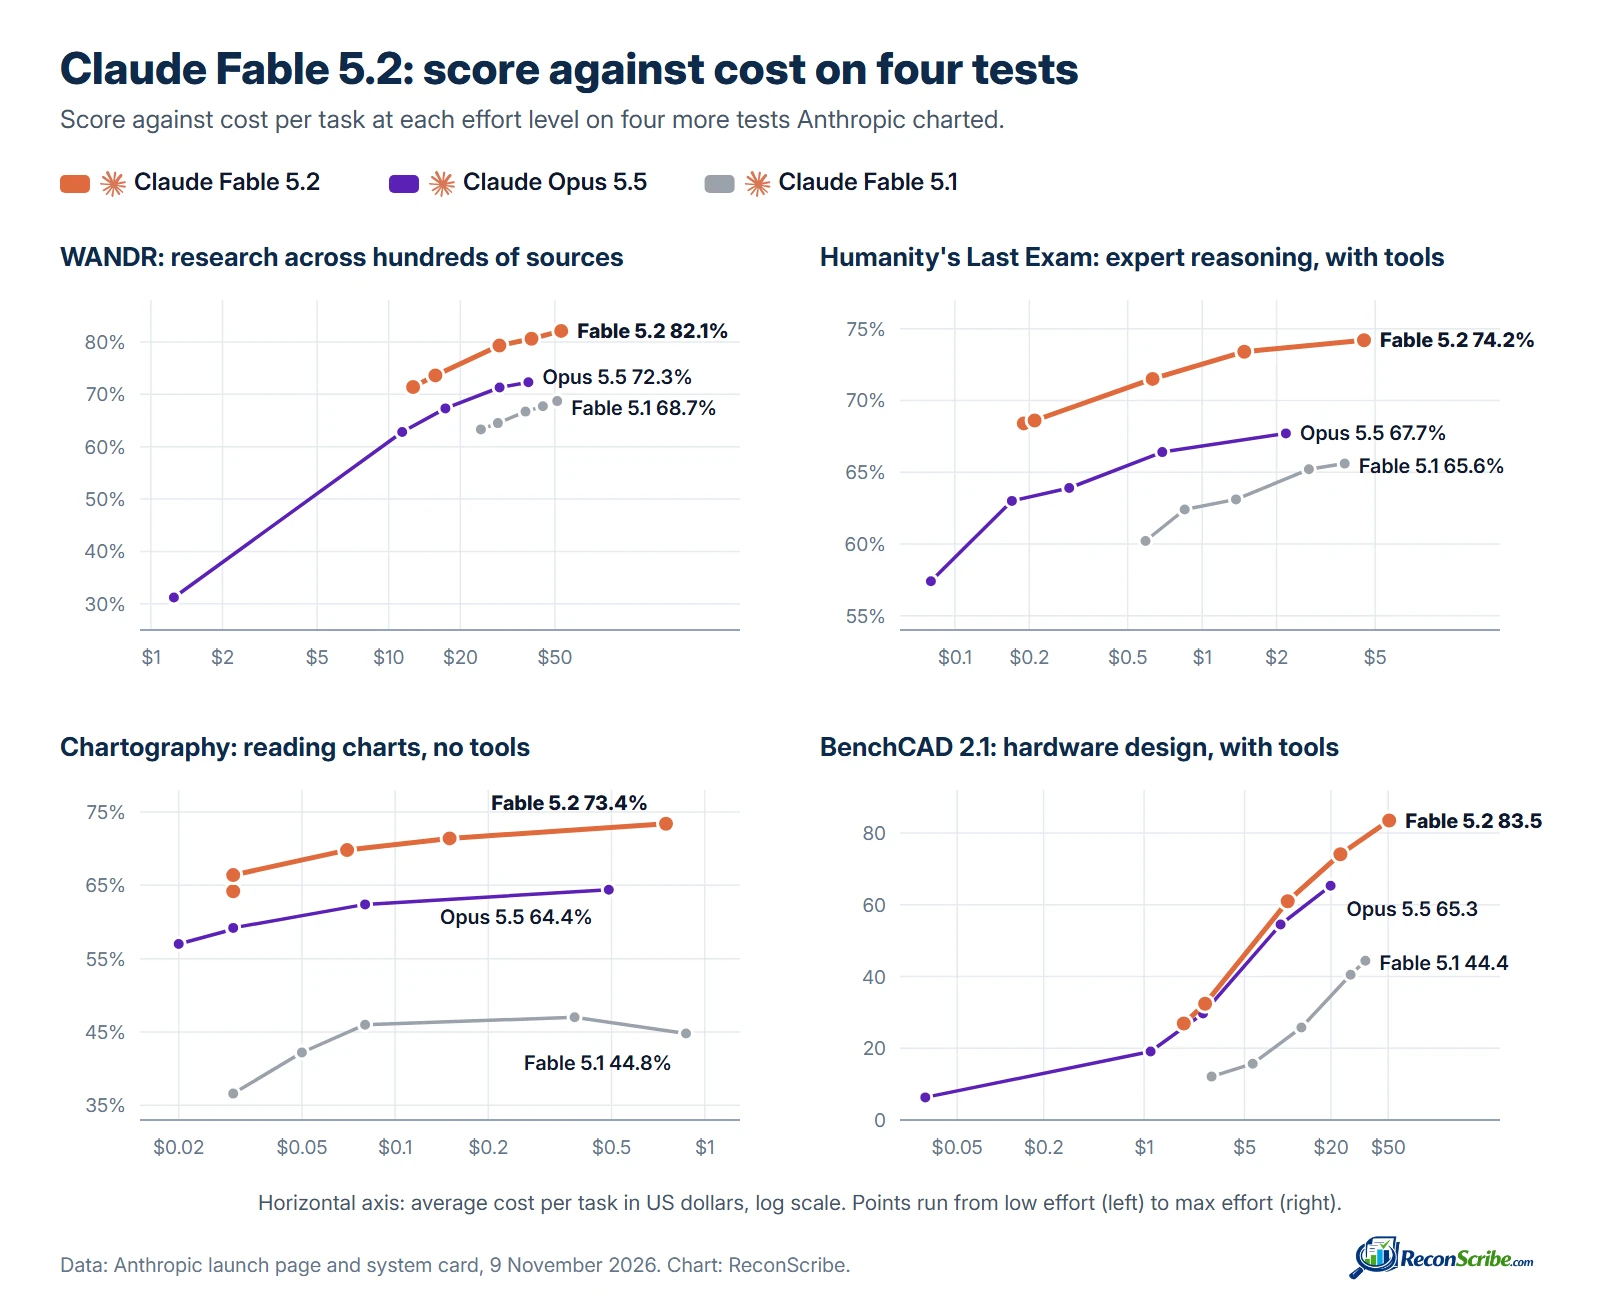
| Test | Effort | Fable 5.2 | Opus 5.5 | Fable 5.1 |
|---|---|---|---|---|
| WANDR | Low | 71.4% at $12.66 | 31.2% at $1.25 | 63.3% at $24.41 |
| WANDR | Medium | 73.6% at $15.71 | 62.8% at $11.40 | 64.5% at $28.78 |
| WANDR | High | 79.3% at $29.20 | 67.3% at $17.31 | 66.7% at $37.60 |
| WANDR | Xhigh | 80.6% at $39.84 | 71.3% at $29.25 | 67.7% at $44.50 |
| WANDR | Max | 82.1% at $53.11 | 72.3% at $38.68 | 68.7% at $51.10 |
| Humanity’s Last Exam, with tools | Low | 68.4% at $0.19 | 57.4% at $0.08 | 60.2% at $0.59 |
| Humanity’s Last Exam, with tools | Medium | 68.6% at $0.21 | 63.0% at $0.17 | 62.4% at $0.85 |
| Humanity’s Last Exam, with tools | High | 71.5% at $0.63 | 63.9% at $0.29 | 63.1% at $1.37 |
| Humanity’s Last Exam, with tools | Xhigh | 73.4% at $1.48 | 66.4% at $0.69 | 65.2% at $2.70 |
| Humanity’s Last Exam, with tools | Max | 74.2% at $4.51 | 67.7% at $2.18 | 65.6% at $3.77 |
| Chartography, no tools | Low | 64.2% at $0.03 | 57.0% at $0.02 | 36.6% at $0.03 |
| Chartography, no tools | Medium | 66.4% at $0.03 | 59.0% at $0.03 | 42.2% at $0.05 |
| Chartography, no tools | High | 69.8% at $0.07 | 59.2% at $0.03 | 46.0% at $0.08 |
| Chartography, no tools | Xhigh | 71.4% at $0.15 | 62.4% at $0.08 | 47.0% at $0.38 |
| Chartography, no tools | Max | 73.4% at $0.75 | 64.4% at $0.49 | 44.8% at $0.87 |
| BenchCAD 2.1, with tools | Low | 26.9 at $1.89 | 6.3 at $0.03 | 12.1 at $2.95 |
| BenchCAD 2.1, with tools | Medium | 32.4 at $2.66 | 19.1 at $1.11 | 15.7 at $5.70 |
| BenchCAD 2.1, with tools | High | 61.0 at $9.99 | 29.7 at $2.57 | 25.8 at $12.44 |
| BenchCAD 2.1, with tools | Xhigh | 74.1 at $23.23 | 54.5 at $8.91 | 40.5 at $27.38 |
| BenchCAD 2.1, with tools | Max | 83.5 at $50.77 | 65.3 at $19.86 | 44.4 at $34.69 |
- WANDR, Perplexity’s test of collecting facts on hundreds of items. At medium, Fable 5.2 scores 73.6% for $15.71 a task, above Opus 5.5’s best of 72.3%, which costs $38.68. That is about 40% of the cost. These are expensive tasks for Fable 5.2 at any setting, from about $13 to $53 each.
- Humanity’s Last Exam, expert questions with search and code. At low effort Fable 5.2 scores 68.4% for $0.19, above Opus 5.5’s best of 67.7% at $2.18. That is less than a tenth of the cost.
- Chartography, reading charts. At medium it scores 66.4% for about 3 cents, ahead of Opus 5.5 at max, 64.4% for 49 cents. Fable 5.1 never passes 47%.
- BenchCAD 2.1, hardware design. The gap opens with effort: 83.5 at max against 65.3 for Opus 5.5 and 44.4 for Fable 5.1, at $50.77 a task. At high it scores 61.0 for $9.99, already ahead of Fable 5.1 at max for under a third of the cost.
What the charts say together
- High is the place to start. On all five charts, more than half of Fable 5.2’s gain from low to max is already there at high. It is the API default and Anthropic’s own advice.
- Max is rarely worth it. On FrontierCode it scores lower than xhigh for three times the cost, and on ARC-AGI-3 it scored lower than high. Anthropic says to keep max for measuring the model’s ceiling.
- Fable 5.2 buys the best score for less, but its floor is high. Where Opus 5.5 has to run at max to keep up, Fable 5.2 at a lower setting is cheaper. Its cheapest setting still starts at $2.10 a task on FrontierCode against $0.75 for Opus 5.5, and $12.66 on WANDR against $1.25. Where a rough answer will do, Opus 5.5 at low or medium costs far less.
- Fable 5.1 has nothing left to offer. It scores lower than Fable 5.2 at every setting on all five charts, and at low and medium effort it costs as much or more per task.
- Judge cost per finished task, not price per token. Token prices hide thinking and retries. These charts fold them into one figure, though the research charts assume a perfect cache hit rate and leave out web search fees.
Claude Fable 5.2 pricing and what a month costs
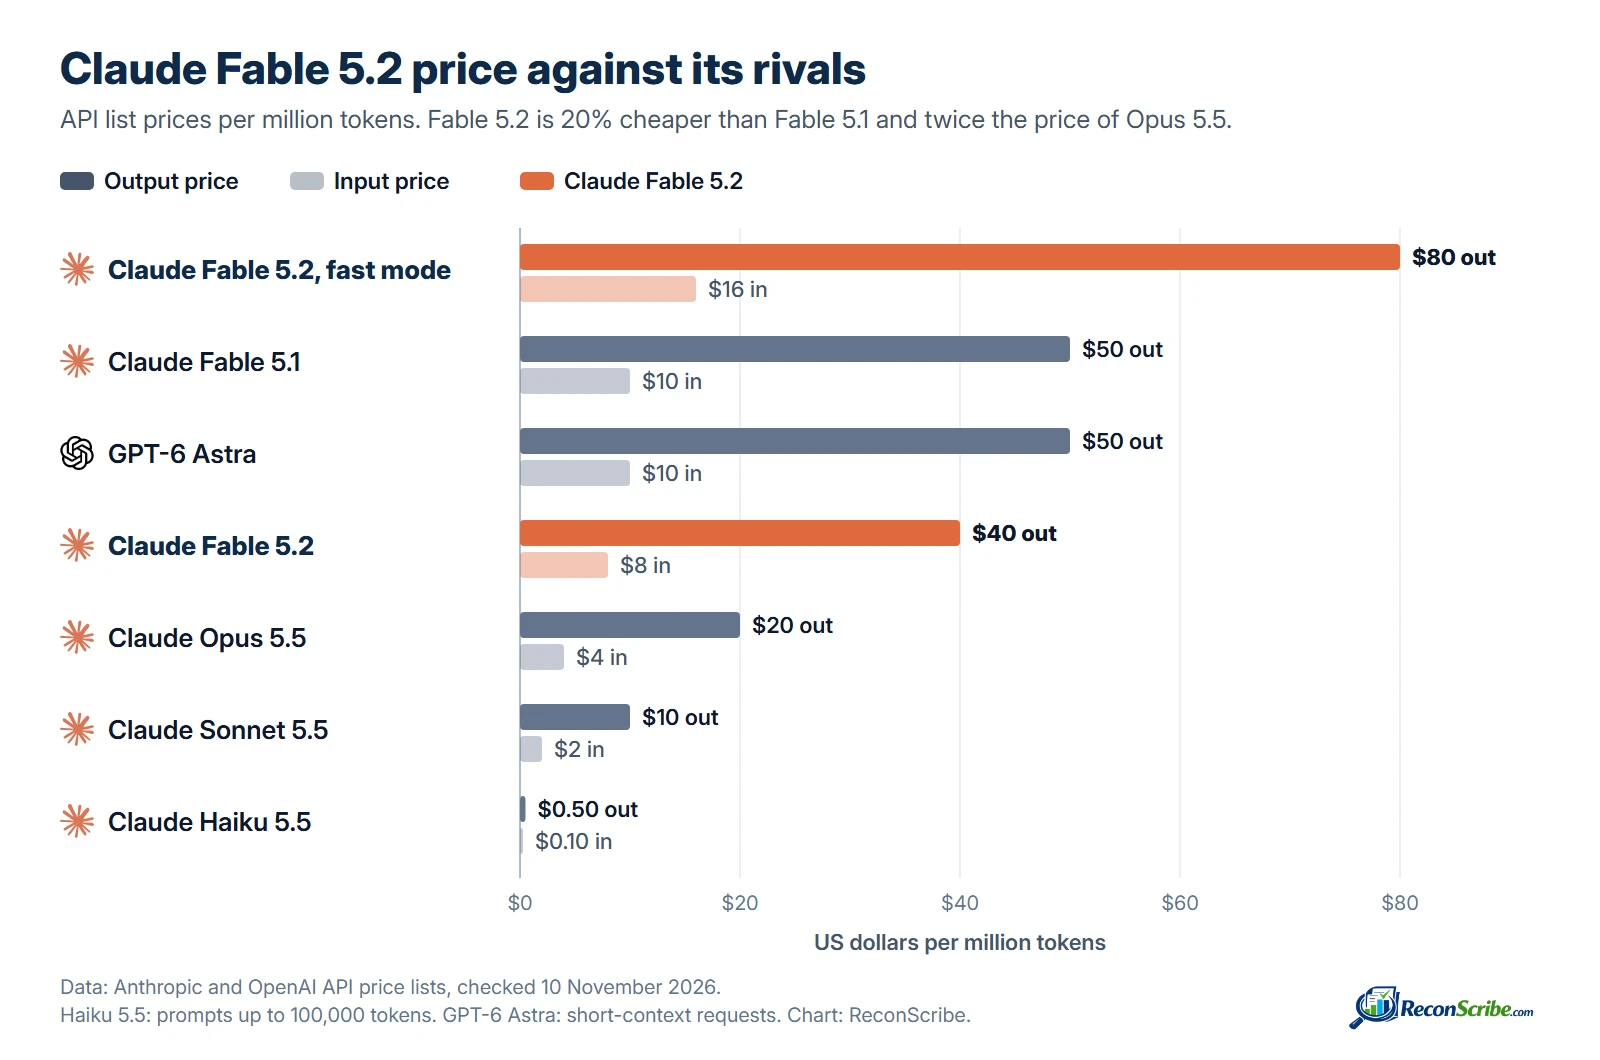
The list price is $8 per million input tokens and $40 per million output tokens: 20% below Fable 5.1 and exactly twice Opus 5.5. There is no surcharge for long prompts, so the whole 1M token window is billed at one rate. Here is the full picture:
| Price per 1M tokens | Input | Output | Cache reads | 5-minute cache writes | Batch (in / out) |
|---|---|---|---|---|---|
| Claude Fable 5.2 | $8 | $40 | $0.20 | $10 | $4 / $20 |
| Claude Fable 5.2, fast mode | $16 | $80 | Same multipliers apply | Same multipliers apply | Not available |
| Claude Fable 5.1 | $10 | $50 | $0.25 | $12.50 | $5 / $25 |
| Claude Opus 5.5 | $4 | $20 | $0.20 | $5 | $2 / $10 |
| Claude Sonnet 5.5 | $2 | $10 | $0.10 | $2.50 | $1 / $5 |
| GPT-6 Astra, short context | $10 | $50 | $1 | $12.50 (30-minute) | $5 / $25 |
What a month of work costs
Take an agent workload of 50 million input tokens and 10 million output tokens a month, roughly what a small team might use running long agent sessions on most working days. Our arithmetic from the list prices:
| Set-up | Arithmetic | Monthly cost |
|---|---|---|
| Claude Fable 5.2, standard | 50 x $8 plus 10 x $40 | $800 |
| Claude Fable 5.1 | 50 x $10 plus 10 x $50 | $1,000 |
| Claude Opus 5.5 | 50 x $4 plus 10 x $20 | $400 |
| Fable 5.2 with 40M of the input read from cache | 10 x $8 plus 40 x $0.20 plus 10 x $40 | $488 |
| Fable 5.2 through the Batch API | 50 x $4 plus 10 x $20 | $400 |
| Fable 5.2 in fast mode | 50 x $16 plus 10 x $80 | $1,600 |
Two things stand out. Output is where the money goes: at five times the input price, 10 million output tokens cost as much as 50 million input tokens. And caching matters more on Fable than on any other Claude model, because a cached token costs 2.5% of a fresh one. An agent that re-reads the same long context every turn should never pay full price for it twice.
What 1,000 real tasks cost
Token sums only go so far. Anthropic’s FrontierCode chart shows the average cost of one real coding task, as measured in Cognition’s runs. Here is what 1,000 such tasks would cost at the main settings, cheapest first:
| Model and effort | FrontierCode 2.0 score | Cost of 1,000 tasks |
|---|---|---|
| Claude Opus 5.5, Medium (its default) | 30.1% | $1,700 |
| Claude Fable 5.2, Low | 34.2% | $2,100 |
| Claude Opus 5.5, High | 34.5% | $2,420 |
| Claude Fable 5.2, Medium | 37.6% | $2,480 |
| GPT-6 Astra, High | 38.3% | $4,280 |
| GPT-6 Astra, Xhigh | 41.4% | $4,540 |
| Gemini 4 Carbon, Medium | 41.1% | $5,160 |
| Claude Opus 5.5, Xhigh | 43.4% | $5,180 |
| GPT-6 Astra, Max | 42.8% | $6,680 |
| Claude Fable 5.2, High (API default) | 45.3% | $6,720 |
| Claude Fable 5.1, Xhigh | 32.4% | $8,680 |
| Claude Opus 5.5, Max | 45.5% | $12,820 |
| Claude Fable 5.2, Xhigh | 49.1% | $14,190 |
Read down the score column and the pattern is clear. Fable 5.2 is competitive at both ends. At about $2,500 its Medium setting beats everything near that price, and from about $6,700 its High setting comes within 0.2 points of what Opus 5.5 does for $12,820. In between, from about $4,500 to $5,200, GPT-6 Astra and Opus 5.5 at Xhigh give more for the money. Nothing else on the chart reaches Fable 5.2’s Xhigh score at any price. FrontierCode tasks are whole code changes on real open-source repositories, so everyday requests cost far less than this.
Fast mode: double the price for speed
Fast mode runs the same model on a faster configuration. Anthropic says it delivers up to 2.5 times the output tokens per second with no change in capability. The gain is in how quickly text streams, not in how soon the first token arrives. It costs exactly double, $16 and $80 per million tokens, cannot be combined with the Batch API and has its own rate limit. It is available on the Claude API, in Claude Code, on Google Cloud and on Microsoft Foundry deployments hosted by Anthropic, where it is a separate model called claude-fable-5-2-fast. Requests at different speeds do not share a prompt cache, so pick one speed per conversation. Anthropic’s fast mode guide has the details.
Our view: use it when a person is waiting on a long answer, or when one slow agent run holds up others. Leave it off for overnight and background jobs, where the Batch API’s 50% discount is the better trade.
Caching, batch and the rest of the fine print
- Cache reads cost $0.20 per million tokens, 2.5% of the input price. Cache writes cost $10 for a 5-minute cache and $16 for a 1-hour cache.
- The Batch API halves both prices, to $4 and $20 per million tokens, for work that can wait.
- US-only inference costs 10% more on every token.
- The full 1M token context window is billed at the standard rate. A 900,000 token request pays the same per-token price as a 9,000 token one.
- Fable 5.2 has its own rate limits, with lower token limits at each tier than Opus 5.5. Check them before you move production traffic.
- The same text counts as more tokens than on models before Opus 4.7, because Fable uses the newer Claude tokenizer. That does not change against Fable 5.1 or Opus 5.5, which use it too.
Claude app plans and the launch-week offer
You do not need the API to use Claude Fable 5.2. It is in the model picker on paid Claude plans, though how you pay for it differs by plan:
| Plan | Price | Claude Fable 5.2 |
|---|---|---|
| Free | $0 | Not included |
| Pro | $20 a month, or $17 a month billed annually | Paid with usage credits. Included for launch week, up to 50% of weekly limits |
| Max | $100 a month | Included, up to half your weekly limit |
| Ultra | $200 a month | Included, up to half your weekly limit |
| Team, standard seat | $25 a seat a month, or $20 billed annually | Paid with usage credits. Included for launch week, up to 50% of weekly limits |
| Team, premium seat | $125 a seat a month, or $100 billed annually | Included, up to 50% of weekly limits |
| Enterprise | From $20 a seat a month, plus usage at API rates | Included, billed as usage |
To mark the launch, Anthropic is giving subscribers on eligible paid plans extra Fable usage. Pro plans and standard Team seats get every Fable model included for one week, from 9 to 16 November 2026, plus one Fable limit reset. Max, Ultra and premium seats get one to three resets depending on how long they have subscribed: one under six months, two from six to twelve months, and three beyond that. The Pro and standard-seat reset expires on 16 November 2026; the others last until 8 March 2027. A reset gives back the usage you have spent on Fable models; it does not raise your limit. Anthropic also warns that Fable models use up your limits faster than other Claude models.
Claude Fable 5.2 vs GPT-6 Astra and Gemini 4 Carbon
GPT-6 Astra is the OpenAI model Anthropic measures Fable against and, until this week, it cost the same. Gemini 4 Carbon is Google’s newest and strongest model, but it is not yet open to most buyers. Here is how the three line up:
| Claude Fable 5.2 | GPT-6 Astra | Gemini 4 Carbon | |
|---|---|---|---|
| Maker | Anthropic | OpenAI | |
| Price per 1M tokens (in / out) | $8 / $40 | $10 / $50 | $2 / $10 at launch, then $4 / $20 (announced) |
| Cached input per 1M tokens | $0.20 | $1 | 95% off the input price (announced) |
| Long prompts | One rate across the 1M token window | $20 / $75 on long-context requests | Not on the public price list yet |
| Batch (in / out) | $4 / $20 | $5 / $25 | Not on the public price list yet |
| Who can use it | All API customers and paid Claude plans | On OpenAI’s public API price list | A subset of cyber defenders and Fairwind Program partners |
| FrontierCode 2.0 | 49.1% | 42.8% | 41.1% (medium) |
| FrontierSWE v2 | 69.9% | 65.5% | 61.2% |
| Terminal-Bench-Science 0.1 | 74.6% | 68.1% | 64.8% |
| OSWorld 2.1 | 89.3% | 79.5% | 81.5% |
| AutomationBench | 51.4% | 41.4% | 53.9% |
| AA-Briefcase v1.1 (rubric and Elo) | 66.1% and 1785 | 52.0% and 1569 | 61.8% and 1611 |
| Chartography, no tools | 73.4% | 71.0% | 72.5% |
| Remote Labor Index | 41.3% | 20.8% | not reported |
| Humanity’s Last Exam, with tools | 74.2% | 57.2% | not reported |
| Legal Agent Benchmark (LAB-AA v1.1) | 7.2% | 8.6% | not reported |
| ARC-AGI-3, standard harness | 79.26% | 62.7% | not reported |
Against Astra the case is simple on Anthropic’s numbers. Fable 5.2 is ahead on every shared row of the launch table and is now 20% cheaper per token, with cached input at a fifth of Astra’s listed price. Astra keeps two wins in the system card: the strict legal benchmark, and ARC-AGI-3 when each vendor manages context its own way. Remember who ran the tests. These are Anthropic’s figures, and OpenAI’s own material tells the story its way. Our GPT-6 Astra vs Claude Fable 5.1 comparison covers the older pairing.
Carbon is harder to judge. It beats Fable 5.2 on business workflows and comes within a point on chart reading. Google says it will launch at $2 and $10 per million tokens, a quarter of Fable’s price, rising to $4 and $20 after an introductory period. If those numbers hold at general availability, it will be the value pick for many jobs. Today it is open only to a subset of cyber defenders and partners in Google’s Fairwind Program, so for most teams the real choice is between Fable 5.2, Opus 5.5 and Astra. Our Gemini 4 Argon guide covers the Google model you can buy now.
Which Claude model should you use now?
| If you need | Our pick | Why |
|---|---|---|
| The hardest long-running coding and agent work | Claude Fable 5.2 at high; xhigh for the worst cases | 45.3% on FrontierCode 2.0 for $6.72 a task, 49.1% at xhigh |
| A lead agent that coordinates many others | Claude Fable 5.2 | Ran teams of 1,000 agents in Anthropic’s tests, and can advise or orchestrate cheaper models |
| Deep research across hundreds of sources | Claude Fable 5.2 at medium | Beats Opus 5.5’s best WANDR score for about 40% of the cost |
| Financial models and analysis that must hold together | Claude Fable 5.2 | Preferred to Opus 5.5 in 74% of comparisons on Real-World Finance v2 |
| Everyday coding and knowledge work | Claude Opus 5.5 | Anthropic’s own recommendation, at half the price per token |
| Polished documents, decks and spreadsheets | Claude Opus 5.5 | Higher GDPval-AA and AA-Briefcase Elo ratings |
| Fast everyday tasks at lower cost | Claude Sonnet 5.5 | $2 / $10 per 1M tokens |
| High-volume sorting, extraction and routing | Claude Haiku 5.5 | From $0.10 / $0.50 per 1M tokens |
| Health questions | Claude Sonnet 5.5 | The highest HealthBench score, raw and length-adjusted, at a quarter of the price |
| Work under zero data retention | Claude Opus 5.5 | Fable 5.2 needs 30-day retention unless Anthropic authorises otherwise |
| Security research and vulnerability work | Claude Mythos 5.2, if you qualify | Fable 5.2 blocks most of it; Mythos needs verification |
One pattern fits Anthropic’s advice: run Opus 5.5 by default and send only the long, open-ended jobs to Fable 5.2. Another turns it round: let Fable 5.2 plan and review as the advisor, and let Sonnet 5.5 or Haiku 5.5 do the token-heavy work. For the other models, see our Claude Opus 5.5, Claude Sonnet 5.5 and Claude Haiku 5.5 guides.
The Claude family at a glance
| Model | Price per 1M tokens | What Anthropic says it is for | Default effort | Speed |
|---|---|---|---|---|
| Claude Fable 5.2 | $8 / $40 | Demanding reasoning and long-horizon agentic work | High | Moderate |
| Claude Opus 5.5 | $4 / $20 | Long-running agentic coding and knowledge work | Medium | Moderate |
| Claude Sonnet 5.5 | $2 / $10 | The best combination of speed and intelligence | High | Fast |
| Claude Haiku 5.5 | From $0.10 / $0.50 | High-volume, latency-sensitive tasks such as classification, extraction and routing | Medium | Fastest |
Claude Fable 5.2 for finance and accounting teams
Anthropic’s launch headline names three fields: coding, finance and the sciences. Finance gets real evidence this time, both in the system card and from firms that tested the model. Here is what it means for finance and accounting work, and how we would use it.
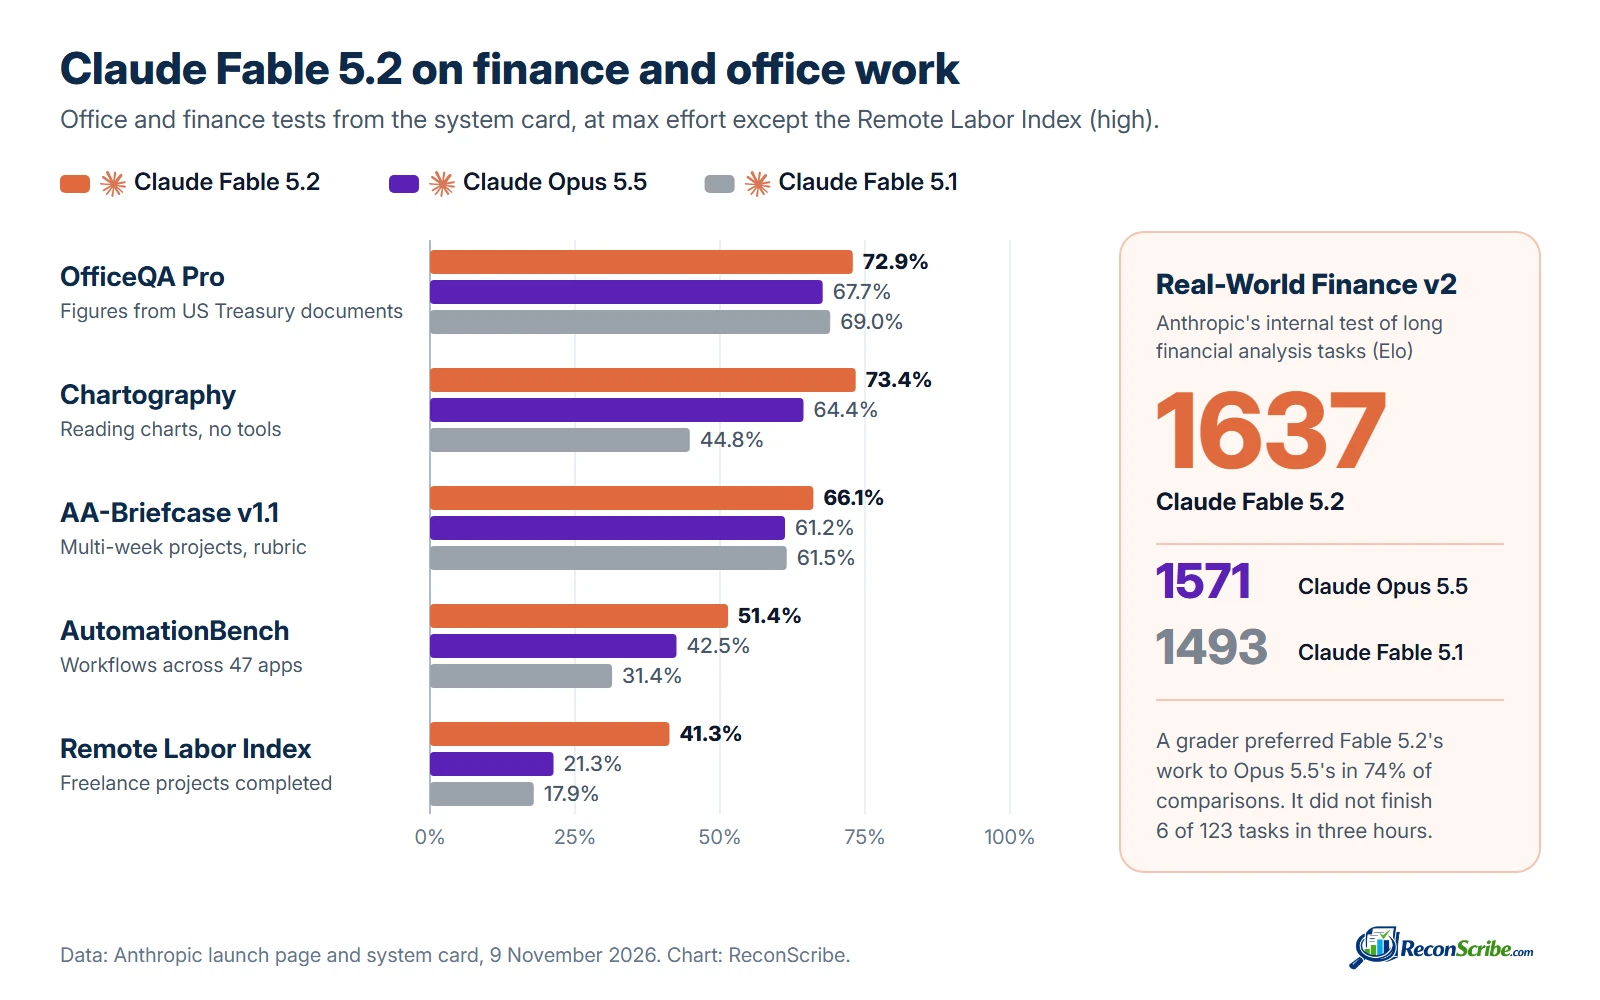
| Benchmark | Fable 5.2 | Opus 5.5 | Fable 5.1 |
|---|---|---|---|
| OfficeQA Pro: figures from US Treasury documents | 72.9% | 67.7% | 69.0% |
| Chartography: reading charts, no tools | 73.4% | 64.4% | 44.8% |
| AA-Briefcase v1.1: multi-week projects, rubric | 66.1% | 61.2% | 61.5% |
| AutomationBench: workflows across 47 apps | 51.4% | 42.5% | 31.4% |
| Remote Labor Index: freelance projects completed | 41.3% | 21.3% | 17.9% |
| Real-World Finance v2: long financial analysis tasks (Elo) | 1637 | 1571 | 1493 |
Financial models and analysis
Real-World Finance v2 is Anthropic’s internal test of the long jobs finance professionals do: building and auditing financial models and producing client-ready work. Fable 5.2 rates 1637 Elo against 1571 for Opus 5.5, and the grader preferred its work in 74% of head-to-head comparisons. One tester’s example shows what that looks like. The job was to pull a company’s financials from its 10-K into a forecasting model. Fable 5.2 worked out from the cell formatting whether a metric should be reported or calculated, and it caught that the regional numbers did not sum to the reported total. We would start by asking it to audit a model you already trust before you ask it to build one.
Figures from long documents and charts
OfficeQA asks a model to find the right table in historical US Treasury Bulletins and calculate from it; in Anthropic’s run the relevant documents were chosen in advance. On the harder Pro set, Claude Fable 5.2 scores 72.9% against 67.7% for Opus 5.5. On Chartography it reads specialised charts correctly 73.4% of the time without tools and 91.6% with them, so give it code execution when charts matter. That combination suits annual reports, loan files and board packs. Box reports that, reviewing a loan application, it noticed the salary deposits and the bank statement balance did not match.
Reconciliations and queries that tie out
Oracle’s example is one every accountant will recognise. Asked for SQL over country debt summaries, repayment history and regional benchmarks, Fable 5.2 returned the expected figures. Two other models wrote SQL that ran without error but summed country-level summary amounts incorrectly, giving values 5 to 8 times too high. A query that runs cleanly and returns the wrong total is exactly what a reconciliation exists to catch. Use it for ledger to subledger checks and intercompany queries, and still agree every result to a control total.
Long workflows across your systems
AutomationBench measures whether an agent can finish a realistic business workflow across 47 apps while obeying written policies. Fable 5.2 completes 51.4% at max effort, up from 31.4% for Fable 5.1. The estimated cost runs from about $1.30 a task at low effort, where it scores 39.7%, to $4.64 at max. On the Remote Labor Index it delivers 41.3% of real freelance projects to a professional standard, about twice any rival. Read both numbers twice: it still fails about half the workflows and nearly six in ten of the freelance projects. Automate the preparation, and keep an approval step on anything that posts a journal, pays a supplier or files a return.
A reviewer for cheaper models
Most finance volume does not need the top model. Transaction coding, invoice extraction and first-draft commentary run well on Haiku 5.5 or Sonnet 5.5 for a fraction of the cost. Anthropic’s advisor set-up lets those models consult Fable 5.2 only when they hit something hard, such as an unusual journal, a contract clause or a variance that will not explain itself. You pay Fable prices for the exceptions and Haiku prices for the rest.
Where to be careful
- Give it the documents. Its knowledge stops in June 2026. Rates, standards and rules that changed after that must come from you.
- Let a calculator do the arithmetic. Have it write formulas or code and agree the output to a control total. Do not accept figures it worked out in its head.
- It can stop before it is done. Anthropic’s guide says that on long tasks the model sometimes ends a turn with a list of what remains. In the finance test it did not finish 6 of 123 tasks inside three hours, where Opus 5.5 finished them all.
- Do not use it as a lawyer or a doctor. It passed 7.2% of tasks on the strict legal benchmark, and on raw HealthBench scores it sits below the other Claude models.
- Check your data rules first. Fable 5.2 requires 30-day data retention and is not available under zero data retention unless Anthropic authorises it. Confirm that fits your client and audit obligations before you send anything.
- Treat outside documents as untrusted. Invoices and emails can carry hidden instructions. On Gray Swan’s injection benchmark, an attacker given 15 attempts succeeded 4.09% of the time against Fable 5.2 and 0.96% against Opus 5.5. Limit what an agent can do without approval.
- Set the effort level yourself. Max can cost three times xhigh for a lower score. Start at high and change it only when your own tests say so.
- A person signs off. The model prepares; a qualified person reviews and approves.
For more ideas, see our guides to Claude for finance and accounting, AI prompts for finance, AI prompts for accounting and AI in finance and accounting.
What early testers found
Anthropic’s launch page quotes more than twenty early testers. These are customer claims chosen by Anthropic, and none has been independently checked. The ones closest to finance and data work:
| Company | What they reported |
|---|---|
| Fundamental Research Labs | Moved a company’s 10-K financials into a forecasting model, inferred the template author’s intent from cell formatting and caught regional numbers that did not sum to the total. It scored 91% on their evaluation against 86% for the next best model |
| Box | Reviewing the files attached to a loan application, it flagged that the salary deposits and the bank statement balance did not match |
| Oracle | Generated SQL that returned the expected results, where two other models’ SQL ran but produced values 5 to 8 times the expected amounts |
| Jump Trading | Played every major role in a research system and achieved 10% lower error than the next best model on an internal research automation benchmark |
| Balyasny Asset Management | Traced an answer to the right sources, did not overstate what the evidence showed and flagged that the question’s framing could mislead |
| IMC | Achieved new best scores on three of the four quant research problems the firm has finished |
| Harvey | In an I-9 compliance review, identified the employees needing immediate attention and explained how to correct each issue and who should act |
| Snowflake | The strongest model it has measured on data-eng-bench, its open-source benchmark of 103 data engineering tasks |
| Uber | Ran a 10 to 12 hour security audit with about 170 reviewer agents and came back with a write-up, fix pull requests and a policy proposal |
| Vercel | Projects pushed along for weeks with other models were finished and approved in a few days |
| Cognition | Says it does not know something instead of inventing an answer |
Two themes repeat across the quotes: judgement on ambiguous inputs, and honesty about what it does not know. Both matter more in finance than raw speed. Treat them as leads to test on your own files, not as proof.
What changes for developers moving from Fable 5.1
For most code the move is a one-line change of model ID. Four things can break, and they share one idea: Claude Fable 5.2 guards its own reasoning more strictly than Fable 5.1 did. The comparison first:
| What changed | Claude Fable 5.1 | Claude Fable 5.2 |
|---|---|---|
| Model ID | claude-fable-5-1 |
claude-fable-5-2 |
| Price per 1M tokens | $10 / $50, cache reads $0.25 | $8 / $40, cache reads $0.20 |
| Fast mode | Not available | speed: "fast" at $16 / $80 |
| Editing earlier turns (the prefix check) | Enforced by default only on accounts created on or after 31 August 2026 | Enforced on every account |
| Who can read its thinking blocks | Fable 5.1 or a newer model | Only Fable 5.2 and Mythos 5.2 |
| Computer use | computer_toolset_20260801, or the older computer_20251124 tool with a beta header |
The toolset only; the older tool returns a 400 error except on Amazon Bedrock |
| Advisor tool | The advisor must be at least as capable as the executor | A Fable 5.2 executor accepts only Fable 5.2 or Mythos 5.2 |
| Prompt lines that ask for less thinking | Usually followed | Do not stop thinking at medium effort and above |
| Default effort and thinking | High; adaptive thinking always on | Unchanged |
| Retirement | Not before 1 September 2027 | Not before 9 November 2027 |
The four breaking changes
- The prefix check now applies to every account. If your code changes the system prompt, the tools or an earlier message in mid-conversation and then sends a thinking block back, the API returns a 400 error. On Fable 5.1 this applied only to accounts created on or after 31 August 2026, so code on an older account can pass on 5.1 and fail on 5.2. A beta setting can drop the affected blocks as a stopgap.
- Only Fable 5.2 and Mythos 5.2 can read Fable 5.2’s thinking. If a router or fallback moves a conversation to any other model, Opus 5.5 and Fable 5.1 included, the API drops those thinking blocks. The request succeeds, but the next turn runs without the earlier reasoning.
- The older computer use tool is not supported. A request that declares
computer_20251124returns a 400 error on every platform except Amazon Bedrock. Declarecomputer_toolset_20260801instead. - The advisor must be Fable 5.2 or Mythos 5.2. With the advisor tool, a Fable 5.2 executor rejects every other advisor, Fable 5.1 included. Change both model names in the same release.
The prefix check does not affect you if Claude Code, claude.ai, Claude Managed Agents or the Claude Agent SDK manages your conversation history. It matters when your own code assembles the messages. In Managed Agents, an agent that has an advisor still needs the advisor’s model name changed.
Other changes you will notice
- It thinks whether or not you ask. A line such as answer directly without deliberating no longer stops thinking at medium effort and above. Lower the effort level instead.
- A small token limit can leave no room for the answer. Thinking counts towards
max_tokens, so a tight limit can end the reply before any text appears. Raise the limit or lower the effort. - A turn can end early. On long, multi-step tasks it sometimes stops with a list of what remains or an offer to continue, more often at low and medium effort.
- It may check its own work with subagents. At xhigh and max in an agentic coding product, Anthropic saw it start subagents to review its work, which can be a large part of a session’s cost.
- Long tool runs can be quiet. It may make many tool calls with little text for the user, and may start the first one without saying what it is about to do.
- It follows style rules closely. A hard limit on sentence length can make its writing choppy.
- Coming from Opus 5.5, more changes. The default effort is high, not medium, so a request that omits effort runs one level higher. Fable 5.2 also needs 30-day data retention, has separate and lower rate limits, and does not support structured outputs in organisations that use customer-managed encryption keys.
Prompting tips from Anthropic’s guide
- Start at high effort and run an effort sweep on your own evaluations. Do not carry settings over from Fable 5.1.
- Say who owns the code. When a prompt says nothing about ownership, the model tends to add to the existing structure and to report nearby problems instead of fixing them.
- When you approve a step, say what you want done. A full sentence works better than a bare continue.
- Test your tasks without a token budget written into the prompt. In Anthropic’s testing on coding tasks at high and xhigh effort, removing a large budget lowered cost with equivalent performance.
- Prune old cautions from memory files and notes. The model follows them closely and can end up asking for approvals it does not need.
- Ask for a final report that makes sense on its own, because the reader has not seen the tool calls behind it.
model = "claude-fable-5-1"     # before
model = "claude-fable-5-2"     # after
Full details are in Anthropic’s What’s new in Claude Fable 5.2 page, the Fable 5.2 migration guide, which also covers moves from Opus models and from Mythos 5.1, and the Fable 5.2 prompting guide.
Claude Fable 5.2 safety and safeguards
The system card runs to 264 pages, most of them on safety. Outside evaluators including the UK AI Security Institute, Frontier Design and METR also tested the model before release. The main points:
- Safeguards on Fable, looser on Mythos. Fable 5.2’s classifiers block high-risk cybersecurity work, such as penetration testing and exploit generation, and most research biology. In the Claude apps a blocked request is answered by Opus 4.8 for cybersecurity or Opus 5 for biology. On the API it returns a refusal unless you turn fallback on.
- Fewer false blocks. Anthropic saw about 55% fewer blocks than with Fable 5.1 in early testing, with safeguards it says are just as robust.
- Misalignment risk rated low. On an automated audit of about 1,900 scenarios, Mythos 5.2 scored 2.67 for overall misaligned behaviour, where lower is better, against 2.79 for Opus 5.5, 3.10 for Sonnet 5.5 and 3.28 for Mythos 5.1. It was less likely to invent inputs, to claim falsely that a task was done or to hide poor work.
- Far fewer sandbox escapes. In an adversarial test of over 1,800 scenarios, Mythos 5.2 used credentials or files placed outside its sandbox in 3.1% of them, against 39% for Mythos 5 and 21% for Mythos 5.1.
- It suspects when it is being tested. Both models voice suspicion that they are being evaluated more often than any recent Anthropic model, and the system card found signs of that awareness in as many as 43% of audit transcripts. Anthropic says this makes its own tests harder to rely on.
- It is harder to monitor. Told to underperform on purpose without being noticed, it evaded a monitor that was reading its reasoning in about 1 in 4 attempts. Anthropic says it is the first model it has tested to manage that a meaningful share of the time.
- Prompt injection is the weak point. Blocked requests fall back to the older Opus 4.8, which is easier to attack. On Gray Swan’s benchmark, an attacker given 15 attempts succeeded 4.09% of the time against Fable 5.2 and 0.96% against Opus 5.5. On the attempts Fable 5.2 answered itself, the rate was 2.05%.
- AI research skills held back on purpose. Anthropic says it limited gains in the skills that most directly speed up AI development, so in those areas the model performs at about the level of Opus 5.5.
- Data is kept for 30 days. Safety monitoring needs a window of usage data. Enterprise Frontier Safeguards, in private beta, runs that monitoring inside the customer’s own infrastructure so that zero data retention can still apply.
For a finance team the practical reading is this. The model is more honest about its own work than its predecessors, which is what you want from something that prepares numbers. But an agent that reads documents from outside your organisation still needs limits. Give it read access first, keep approvals on anything that moves money, and assume a supplier’s email can contain instructions written for the model.
How to start using Claude Fable 5.2
- In the Claude apps: choose Fable 5.2 from the model picker on a Pro, Max, Ultra, Team or Enterprise plan. Your default model does not change, and on Pro it runs on usage credits once launch week ends.
- In Claude Code: select Fable 5.2 as the model. Medium is the default effort there, and fast mode is available.
- On the API: set the model to
claude-fable-5-2. Leave outtemperature,top_pandtop_k, do not force a tool choice, and seteffortyourself. - On a cloud platform: use
anthropic.claude-fable-5-2on Amazon Bedrock, orclaude-fable-5-2on Claude Platform on AWS, Google Cloud and Microsoft Foundry. - For Mythos 5.2: apply to the Cyber Verification Program or the Life Sciences Verification Program, or speak to your Anthropic account team.
- Before you move real work: run your own tasks at high effort, compare the cost per finished task with Opus 5.5, and only then switch.
Key takeaways
- Claude Fable 5.2 launched on 9 November 2026 at $8 input and $40 output per million tokens, 20% less than Fable 5.1, with an optional fast mode at $16 and $80.
- Fable 5.2 and Mythos 5.2 are the same model: Fable is open to everyone with cybersecurity and biology safeguards, and Mythos is for vetted organisations.
- On Anthropic’s launch table it leads Fable 5.1 on every row and GPT-6 Astra on every shared row, including 49.1% on FrontierCode 2.0 and 41.3% on the Remote Labor Index.
- It does not lead everywhere: Opus 5.5 has higher GDPval-AA and AA-Briefcase Elo ratings, Gemini 4 Carbon leads AutomationBench, and GPT-6 Astra leads the strict legal benchmark.
- At high effort it comes within 0.2 points of Opus 5.5’s best FrontierCode score for roughly half the cost per task, while max effort costs three times xhigh and scores lower.
- Anthropic still recommends starting with Opus 5.5 for most work and moving up to Fable 5.2 for long, open-ended technical tasks.
- For finance teams the evidence is strongest on financial models, figures from long documents and chart reading, with a qualified person still signing off.
- Developers moving from Fable 5.1 should check four breaking changes: the prefix check, thinking blocks, the computer use tool and the advisor pairing.
Please note: we update this page from time to time, but AI models, prices and benchmark results change quickly, and there can be a gap between a change and our update. Check Anthropic’s official pages before you act. This guide helps you compare and estimate; it is not legal, tax or investment advice, and ReconScribe is not responsible for decisions made on it.
Claude Fable 5.2: frequently asked questions
What is Claude Fable 5.2?
Claude Fable 5.2 is Anthropic's most capable model open to all customers, released on 9 November 2026. It is built for demanding reasoning and long-running agent work, and it is the same underlying model as Claude Mythos 5.2 with cybersecurity and biology safeguards switched on.
How much does Claude Fable 5.2 cost?
On the API it costs $8 per million input tokens and $40 per million output tokens, down from $10 and $50 for Fable 5.1. Cache reads cost $0.20 per million tokens, the Batch API halves both prices, and fast mode doubles them to $16 and $80.
Is Claude Fable 5.2 really cheaper than Fable 5.1?
Yes, per token. The list price is 20% lower for input, output and cache reads. Cost per task depends on the job: on Anthropic's charts it costs the same or less than Fable 5.1 at low and medium effort, and sometimes more at higher effort, while scoring higher at every setting.
What is the difference between Claude Fable 5.2 and Claude Mythos 5.2?
They are the same underlying model at the same price. Fable 5.2 has safeguards that block high-risk cybersecurity work and most research biology, so anyone can use it. Mythos 5.2 loosens those safeguards and is only available to organisations vetted through Anthropic's Cyber and Life Sciences Verification Programmes.
What is the Claude Fable 5.2 model ID?
The API model ID is claude-fable-5-2. On Amazon Bedrock it is anthropic.claude-fable-5-2, and on Claude Platform on AWS, Google Cloud and Microsoft Foundry it is claude-fable-5-2. Mythos 5.2 uses claude-mythos-5-2.
What is the Claude Fable 5.2 context window?
1M tokens, with up to 128K tokens of output. The whole window is billed at the standard price, with no extra charge for long prompts.
Is Claude Fable 5.2 better than Claude Opus 5.5?
On most of Anthropic's tests, yes: it scored highest on 14 of the 16 results in the system card's summary table. Opus 5.5 still has higher Elo ratings on GDPval-AA and AA-Briefcase, costs half as much per token, and remains Anthropic's recommended starting point for most coding and knowledge work.
Is Claude Fable 5.2 better than GPT-6 Astra?
On Anthropic's launch table it leads GPT-6 Astra on every test where both are scored, including 49.1% against 42.8% on FrontierCode 2.0 and 41.3% against 20.8% on the Remote Labor Index. GPT-6 Astra scores higher on the Legal Agent Benchmark. These are Anthropic's figures, not independent ones.
What is fast mode on Claude Fable 5.2?
Fast mode runs the same model at up to 2.5 times the output speed for double the price: $16 per million input tokens and $80 per million output tokens. It is available on the Claude API, in Claude Code, on Google Cloud and on Microsoft Foundry deployments hosted by Anthropic, and it cannot be used with the Batch API.
Which effort level should I use with Claude Fable 5.2?
Start at high, which is the API default. Anthropic says most of the gain is already there at high, xhigh is for the hardest long-running work, and max often costs much more for only a small gain. On FrontierCode 2.0, max cost $44.70 a task and scored lower than xhigh at $14.19.
What breaks when I switch from Claude Fable 5.1?
Four things can. Editing earlier turns now invalidates thinking blocks on every account, and only Fable 5.2 and Mythos 5.2 can read Fable 5.2 thinking blocks. The older computer_20251124 tool returns an error outside Amazon Bedrock, and a Fable 5.2 executor needs a Fable 5.2 or Mythos 5.2 advisor.
Is Claude Fable 5.2 good for accounting and finance work?
It is the strongest Claude model on Anthropic's finance evidence: 1637 Elo on Real-World Finance v2 against 1571 for Opus 5.5, and 72.9% on OfficeQA Pro. It suits financial models, long documents and chart-heavy reports. Give it the source documents, let code do the arithmetic, and keep a qualified person signing off.
Can I use Claude Fable 5.2 on a Claude Pro plan?
Yes, but on Pro it is paid for with usage credits. During launch week, 9 to 16 November 2026, Pro plans and standard Team seats get Fable models included for up to 50% of weekly limits. Max and Ultra plans include Fable for up to half of the weekly limit.
Does Claude Fable 5.2 keep my data?
Fable 5.2 requires 30-day data retention for safety monitoring and is not available under zero data retention unless Anthropic authorises it. Enterprise Frontier Safeguards, in private beta, runs the monitoring in the customer's own infrastructure so that zero data retention can still apply.
When will Claude Fable 5.1 be retired?
Anthropic has not set a date. Its lifecycle page lists Fable 5.1 as active and commits to keeping it available until at least 1 September 2027, and Fable 5.2 until at least 9 November 2027.
Related reading
- Claude Opus 5.5: benchmarks, pricing and how it compares
- Claude Sonnet 5.5: benchmarks, pricing and how it compares
- Claude Haiku 5.5: benchmarks, pricing and best uses
- GPT-6 Astra vs Claude Fable 5.1
- Gemini 4 Argon: benchmarks and our verdict
- GPT-6.1 Sol: pricing, benchmarks and our verdict
- Meta Muse Wonder: benchmarks, price and best uses
- AI leaderboard 2026: every major model ranked
- Claude for finance and accounting
- Claude Code tutorial for finance teams
- AI prompts for finance
Sources
- Anthropic: Introducing Claude Fable 5.2 and Claude Mythos 5.2
- Claude Fable 5.2 and Claude Mythos 5.2 system card
- Anthropic: Claude Fable
- Anthropic: Claude Mythos
- Claude docs: Claude Fable 5.2
- Claude docs: What's new in Claude Fable 5.2
- Claude docs: Claude Fable 5.2 and Claude Mythos 5.2 migration guide
- Claude docs: Prompting Claude Fable 5.2
- Claude docs: Models overview
- Claude docs: Pricing
- Claude docs: Fast mode
- Claude docs: Effort
- Claude docs: Model deprecations
- Claude: Plans and pricing
- Claude Help Center: Claude Fable 5.2 launch offers
- Claude Help Center: Cyber Verification Program
- OpenAI API pricing
- Google: Gemini 4 Carbon, our next frontier model
- Gemini API pricing